Most of my work is driven by the same instinct: to treat data—whether an image, a gait sequence, or a spatial audio scene—as a signal, and to look for the structure beneath it. I earned my M.S. in Artificial Intelligence at Ewha Womans University, where I conducted research in the PAI Lab under the supervision of Prof. Junhyug Noh. I now work in the same lab as a researcher, spanning computer vision, multimodal AI, and generative modeling.
Experience
Conducted research on diffusion-based defect image generation for industrial visual inspection. Designed an end-to-end pipeline encompassing data preprocessing, model training, synthetic defect generation, and performance evaluation.
Publications
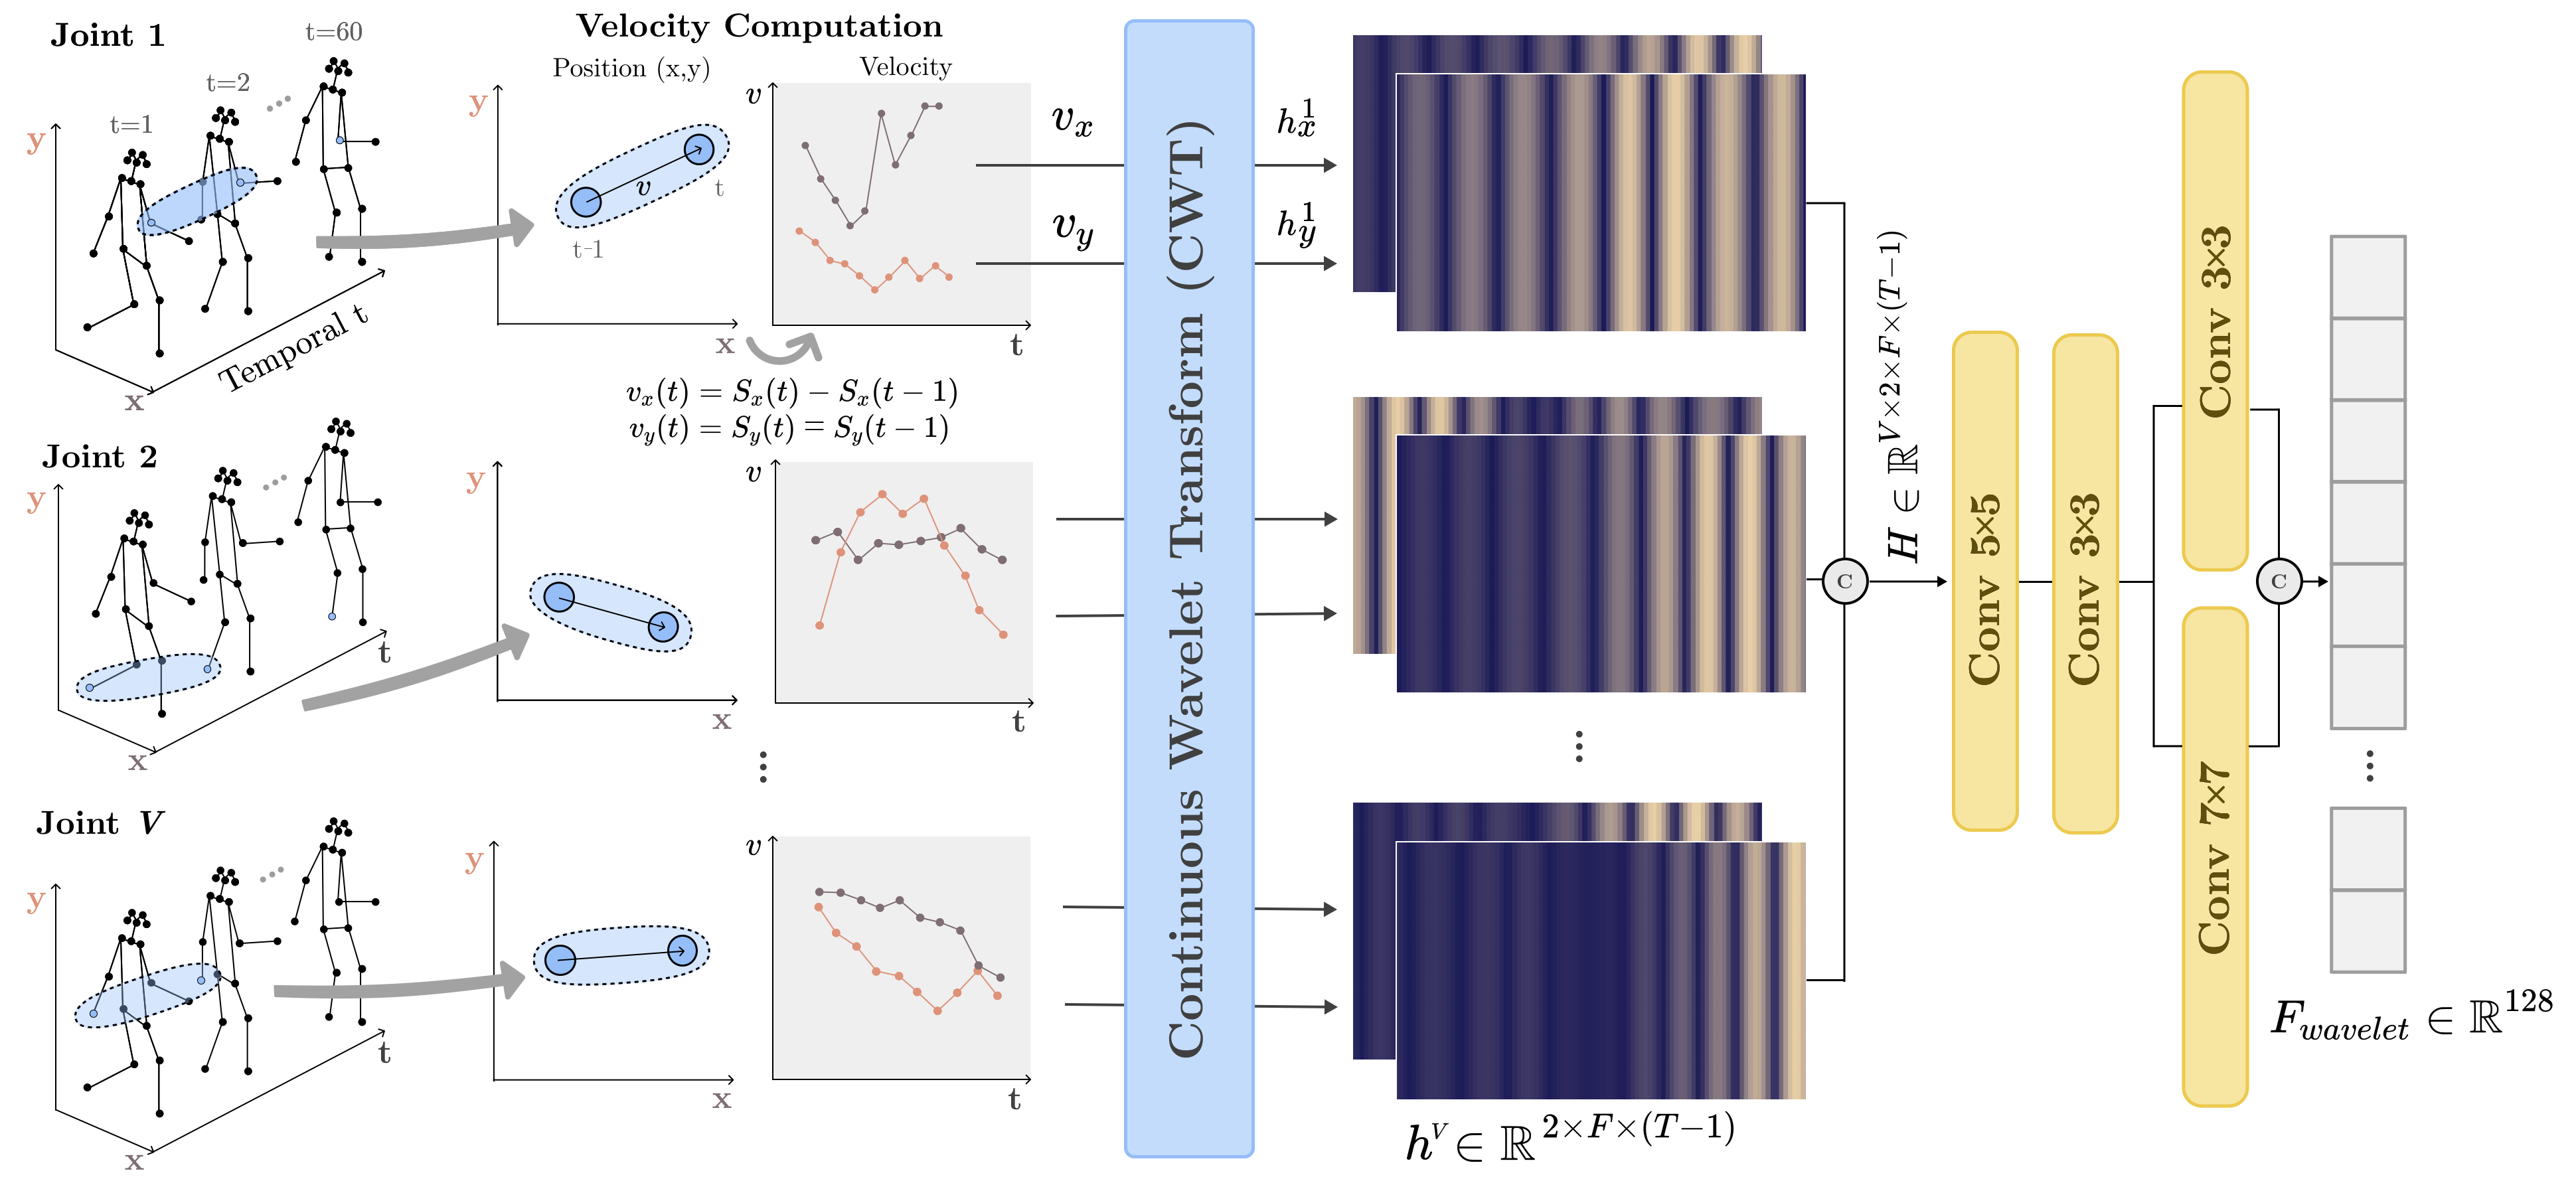
Explicit Time-Frequency Dynamics for Skeleton-Based Gait Recognition
We propose a plug-and-play Wavelet Feature Stream that enriches skeleton-based gait recognition by capturing time-frequency dynamics of joint velocities via Continuous Wavelet Transform (CWT). A lightweight multi-scale CNN extracts discriminative features from the resulting scalograms and fuses them with any existing backbone, requiring no architectural changes or extra supervision. The method consistently improves strong baselines on CASIA-B, with especially notable gains under covariate shifts such as bag-carrying and coat-wearing conditions.
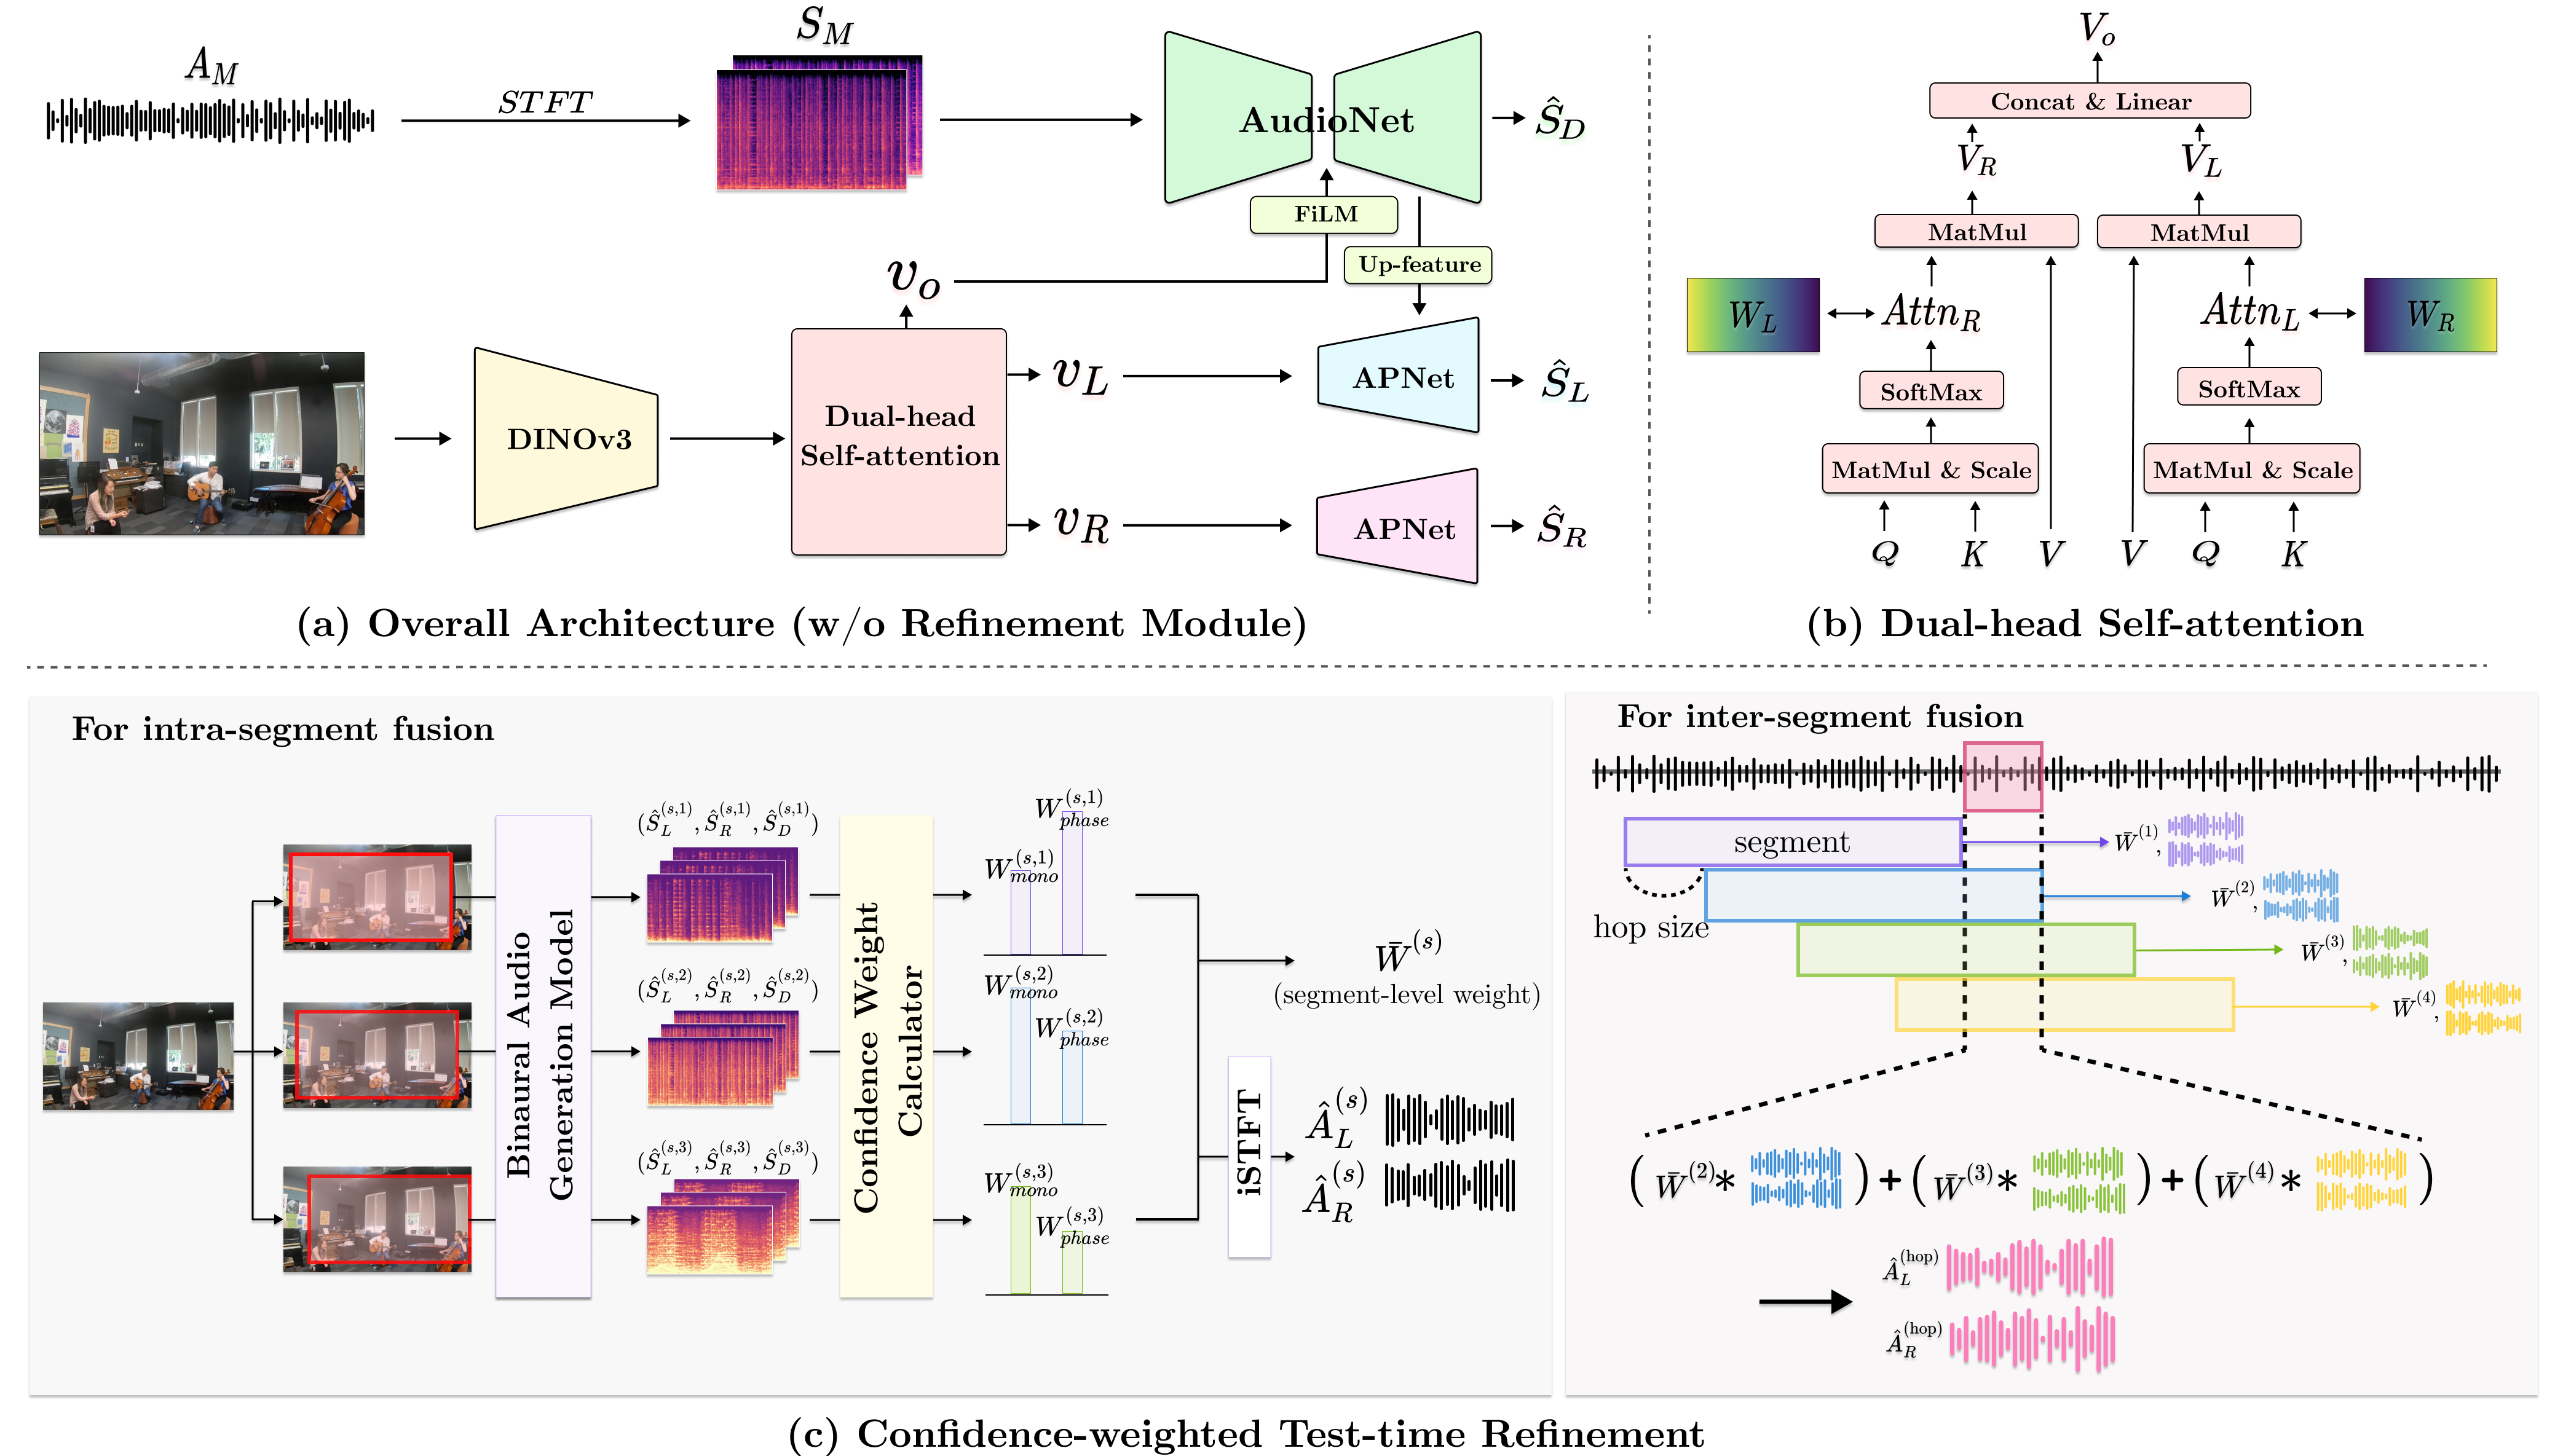
SIREN: Spatially-Informed Reconstruction of Binaural Audio with Vision
SIREN reconstructs binaural audio from monaural sound and visual context by directly predicting the left and right channels. Its ViT-based encoder combines dual-head self-attention with a softly annealed spatial prior to capture shared scene representations and spatially grounded left/right cues. A two-stage, confidence-weighted waveform fusion strategy further suppresses crosstalk across multiple crops and overlapping windows using mono reconstruction confidence and interaural phase consistency. The framework improves time-frequency and phase-sensitive reconstruction quality on FAIR-Play and MUSIC-Stereo without requiring task-specific spatial annotations
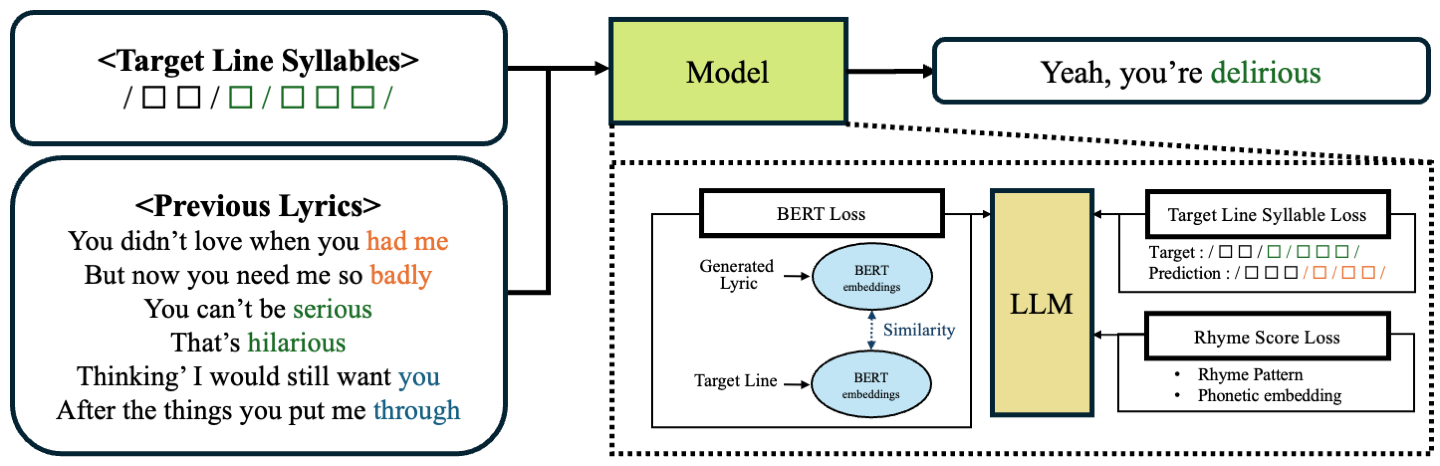
LYRICS: Line-by-Line Lyric Generation with Joint Control of Syllables, Context, and Rhyme
Designed as a collaborative tool for songwriters, LYRICS generates lyrics one line at a time while jointly controlling syllabic structure, local context, and phonetic rhyme. The framework fine-tunes LLaMA 3.1 (8B) with a user-defined syllable template and a multi-objective loss that promotes syllable alignment, contextual consistency, and rhyme quality. Experiments on a curated popular-music corpus demonstrate improved semantic and structural quality over a cross-entropy-only baseline while preserving fine-grained creative control.
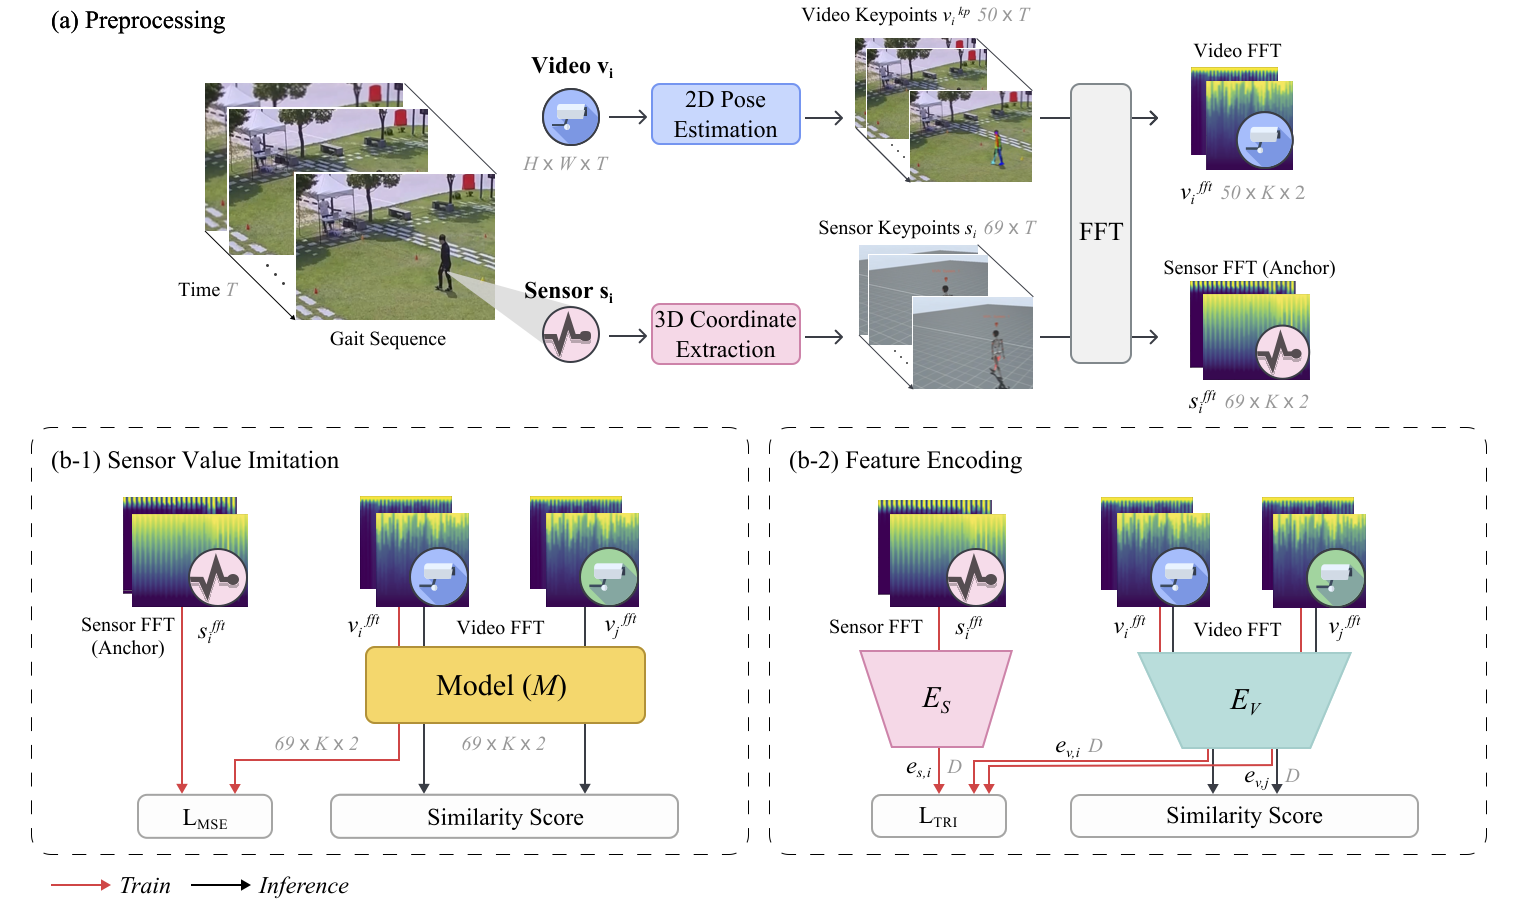
Toward Robust Gait Identification: A Frequency Domain Approach in Varied Surveillance Environments
We propose a frequency domain-based gait recognition framework using FFT on openpose keypoints, integrating video and IMU sensor data. To support this, we introduce the E-GAITS dataset covering diverse surveillance conditions (indoor/outdoor, varying lighting). Our method achieves high recognition accuracy, with IMU integration particularly boosting performance in low-light environments.